AutoPatchBench
 Llama 3.3 70B Instruct 11.5% leads since April 2025
Agents write security patches for crashes that a fuzzer found in native code. Fixes are checked by fuzzing and differential debugging.
Introduced with CyberSecEval 4. Built on ARVO, a set of reproducible C and C++ crashes. Run with the autopatch flag.
- Made by
- Meta (PurpleLlama)
- Released
- April 2025
- Kind
- Secure code and review
- Level
- Expert
- Scored
- Checked automatically
- Answers
- Agent task
- Tasks
- All public
- Strongest model tested
- Claude 3.7 Sonnet #118 on the capability index
- Last model added
- April 2025
- Scores refreshed
- November 12th, 2026
Llama 3.3 70B Instruct leads with 11.5% among models released by April 2025
Best score per entry from the benchmark's own leaderboard, read on November 12th, 2026. Where a model ran with several settings or harnesses, we keep its best. Names in gray aren't in our model list: fine-tunes, agent systems, products and older models. They don't count toward leaders.
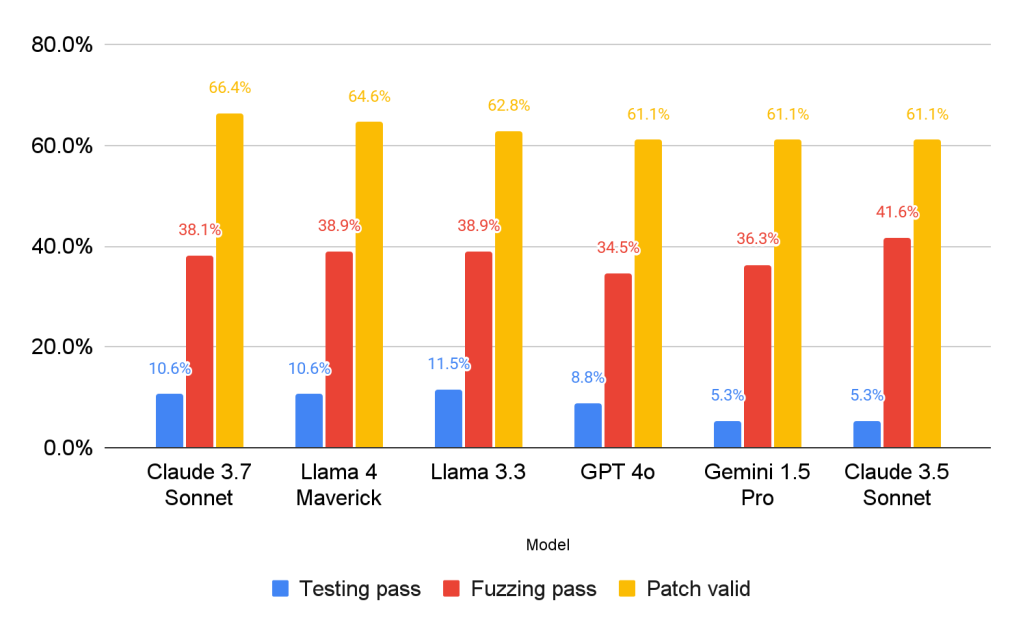
The newest model with a score here came out in April 2025, and nobody has tested a newer one. Among the 20 highest-ranked models on the capability index, these have no score yet:
- Claude Fable 5.2
-
 Gemini 4 Carbon
- GPT-6 Astra
- Claude Opus 5.5
- and 16 more
- 1 Llama 3.3 70B Instruct 11.5%
- 2 Claude 3.7 Sonnet 10.6%
- 3 Llama 4 Maverick 10.6%
- 4 GPT-4o (snapshot unspecified) 8.80%
- 5 Claude 3.5 Sonnet (snapshot unspecified) 5.30%
- 6 Gemini 1.5 Pro (snapshot unspecified) 5.30%
Source: Official AutoPatchBench leaderboard
| # | Entry | Score | Setting | Date | Source |
|---|---|---|---|---|---|
| 1 | Llama 3.3 70B Instruct | 11.5% | Dec 2024 | Official leaderboard | |
| 2 | Claude 3.7 Sonnet | 10.6% | Feb 2025 | Official leaderboard | |
| 3 | Llama 4 Maverick | 10.6% | Apr 2025 | Official leaderboard | |
| 4 | GPT-4o (snapshot unspecified) | 8.80% | Official leaderboard | ||
| 5 | Claude 3.5 Sonnet (snapshot unspecified) | 5.30% | Official leaderboard | ||
| 6 | Gemini 1.5 Pro (snapshot unspecified) | 5.30% | Official leaderboard |
Number one over time
Lab claims count from the day the card came out, independent runs from the model’s release.
Source: Official AutoPatchBench leaderboard
Scores over time
All the scores we have, one dot each, so a model tested at several settings appears more than once.
Source: Official AutoPatchBench leaderboard
No lab model card reports it yet
We read the headline results of 522 launch posts from 52 labs, and none of them list this benchmark.
More in Cybersecurity
- ExploitGym In use 869 real-vulnerability exploit-development tasks (userspace, V8, Linux kernel). Success means capturing a flag through the intended vulnerability. GPT-6 Astra 42.4%
- ExploitBench In use 41 recent V8 JavaScript-engine N-day vulnerabilities. Progress measured by 16 grader-verified capability flags across five tiers. GPT-6 Astra 100%
- CyberBench v1.1 (Vals) In use Agents work on OSS-Fuzz memory-safety bugs from ARVO images in two tracks. They write a proof-of-concept input that crashes the target, or patch the source so the crash stops and tests still pass. Muse Wonder 80.4%
- SRE-Bench In use Software reverse engineering without source: 262 binary instances from 19 private programs, each with six graded objectives. GPT-6 Astra 56.9%
- CyScenarioBench In use Scenario-based long-horizon security challenges in sandboxes, organized in task, scenario and campaign tiers. Evaluation set kept private. Gemini 4 Argon 100%
- ExploitBench - Internal Port In use Agents develop working exploits for recently disclosed vulnerabilities to limit contamination. Scored as arbitrary code execution success rate. GPT-6 Cyber 42%