Instrument reading (Google DeepMind)
 Gemini Robotics ER 2 65.7% leads since July 2026 Gemini Robotics-ER 1.6 93% leads since April 2026
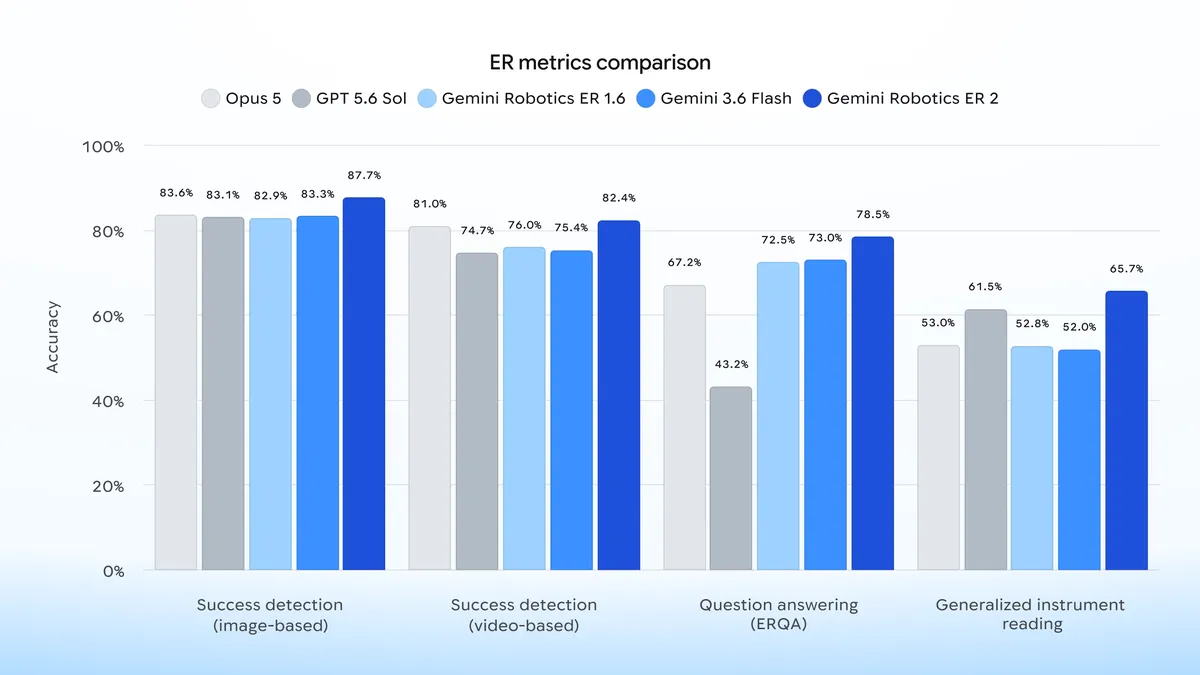
Models read gauges, sight glasses, digital displays, linear scales, rulers and thermometers from robot camera images. ER 2 tests 10 instrument types.
Introduced with Gemini Robotics-ER 1.6 in 2026-04 with Boston Dynamics inspection use cases and generalized in the ER 2 post.
- Made by
- Google DeepMind
- Released
- April 2026
- Kind
- Embodied reasoning
- Level
- Everyday
- Scored
- Checked automatically
- Answers
- Short answer
- Tasks
- Kept private
- Strongest model tested
- Claude Opus 5 #10 on the capability index
- Last in a launch post
- July 2026, dropped after it saturated
- Last model added
- July 2026
- Scores refreshed
- November 12th, 2026
Gemini Robotics ER 2 leads with 65.7% among models released by July 2026
Best score per model from the benchmark's own leaderboard, read on November 12th, 2026. Where a model ran with several settings or harnesses, we keep its best.
Gemini Robotics-ER 1.6 leads with 93%, claims included
Best score per model from every source, including labs’ own numbers and claims Epoch AI collected from reports and papers. Labs pick their own settings, so a claim can beat an independent run of the same model.
The newest model with a score here came out in July 2026, and nobody has tested a newer one. Among the 20 highest-ranked models on the capability index, these have no score yet:
- Claude Fable 5.2
- Gemini 4 Carbon
- GPT-6 Astra
- Claude Opus 5.5
- and 14 more
- 1 Gemini Robotics ER 2 65.7%
- 2 GPT-5.6 Sol 61.5%
- 3 Claude Opus 5 53%
- 4 Gemini Robotics-ER 1.6 52.8%
- 5 Gemini 3.6 Flash 52%
Source: Official Instrument reading (Google DeepMind) leaderboard
- 1 Gemini Robotics-ER 1.6 93%
- 2 Gemini Robotics ER 2 65.7%
- 3 GPT-5.6 Sol 61.5%
- 4 Claude Opus 5 53%
- 5 Gemini 3.6 Flash 52%
Sources: Labs’ model cards and official Instrument reading (Google DeepMind) leaderboard
| # | Model | Score | Setting | Date | Source |
|---|---|---|---|---|---|
| 1 | Gemini Robotics ER 2 | 65.7% | Jul 2026 | Official leaderboard | |
| 2 | GPT-5.6 Sol | 61.5% | Jul 2026 | Official leaderboard | |
| 3 | Claude Opus 5 | 53% | Jul 2026 | Official leaderboard | |
| 4 | Gemini Robotics-ER 1.6 | 52.8% | Apr 2026 | Official leaderboard | |
| 5 | Gemini 3.6 Flash | 52% | Jul 2026 | Official leaderboard |
| # | Model | Score | Setting | Date | Source |
|---|---|---|---|---|---|
| 1 | Gemini Robotics-ER 1.6 | 93% | Apr 2026 | Lab model card | |
| 2 | Gemini Robotics ER 2 | 65.7% | Jul 2026 | Official leaderboard | |
| 3 | GPT-5.6 Sol | 61.5% | Jul 2026 | Official leaderboard | |
| 4 | Claude Opus 5 | 53% | Jul 2026 | Official leaderboard | |
| 5 | Gemini 3.6 Flash | 52% | Jul 2026 | Official leaderboard |
Labs report scores for 2 models in their cards. Switch the scores above to rank them together.
3 models have held number one on the official leaderboard since its release in April 2026 Number one over time
Lab claims count from the day the card came out, independent runs from the model’s release.
Source: Official Instrument reading (Google DeepMind) leaderboard
Google DeepMind’s own number for Gemini Robotics-ER 1.6 passed 85% in April 2026
All the scores we have, one dot each, so a model tested at several settings appears more than once.
Sources: Official Instrument reading (Google DeepMind) leaderboard and labs’ model cards
Labs headline it less often now, last in July 2026
Launch posts from every lab that has listed it, one tick per post. Tall colored ticks include it, and short gray ones leave it out.
| Date | Launch post | Score | As the post writes it |
|---|---|---|---|
| Jul 30, 2026 | Gemini Robotics ER 2 | 65.7 | Generalized instrument reading |
| Apr 14, 2026 | Gemini Robotics-ER 1.6 | 93 | Instrument Reading w/ agentic vision |
2 lab claims next to the leaderboard
Each score a lab reported for its own model, beside the same model's best score on the leaderboard. Gaps mostly come from different harnesses, effort levels and task subsets. 1 of them match, which usually means one side copied the other. Every benchmark.
| Model | Lab says | Board says | Gap |
|---|---|---|---|
| Gemini Robotics-ER 1.6 | 93% Instrument Reading w/ agentic vision | 52.8% Leaderboard | +40 pts |
| Gemini Robotics ER 2 | 65.7% Generalized instrument reading | 65.7% Leaderboard | Same |
More in Robotics
- ERQA In use 400 multiple-choice visual questions from robot and egocentric footage on spatial, trajectory, action and state reasoning. Accuracy. Gemini Robotics ER 2 78.5%
- RoboDojo In use Generalist manipulation policies run 42 Isaac Sim tasks and 18 remote real-robot tasks. Scored by task score and success rate. GPT-6 Astra 29%
- RoboLab In use Zero-shot DROID Franka policies in Isaac Lab on 120 tabletop tasks at three instruction levels, 10 episodes each. Success rate. FLUX 3 Action 42.9%
- Progress classification (Google DeepMind) In use Models assign each frame of a robot video to one of five task-progress bands from 0 to 100 percent. Scored by accuracy. Gemini Robotics ER 2 57.4%
- Human proximity (Google DeepMind robotics) In use Models judge from robot camera views whether a human is within 1 meter, a spatial awareness check for safe robot behavior. Scored by accuracy. Gemini Robotics ER 2 93%
- Moment finding (Google DeepMind) In use Models find the moment in a robot video when an event happens. Scored by accuracy and mean absolute time distance in seconds. Gemini Robotics ER 2 91.3%