MM-ClawBench
Agents complete common OpenClaw tasks such as study planning, office documents, scheduled research, and code maintenance. Scoring is accuracy.
In-house: MiniMax never released the tasks or explained the scoring.
- Made by
- MiniMax
- Released
- March 2026
- Kind
- General assistants
- Level
- Everyday
- Scored
- Graded by a model
- Answers
- Agent task
- Tasks
- Kept private
- Strongest model tested
- GPT-5.4 #27 on the capability index
- Last in a launch post
- March 2026, dropped before it saturated
- Last model added
- May 2026
- Scores refreshed
- November 12th, 2026
Claude Opus 4.6 leads with 75.4% among models released by March 2026
Best score per model from the benchmark's own leaderboard, read on November 12th, 2026. Where a model ran with several settings or harnesses, we keep its best.
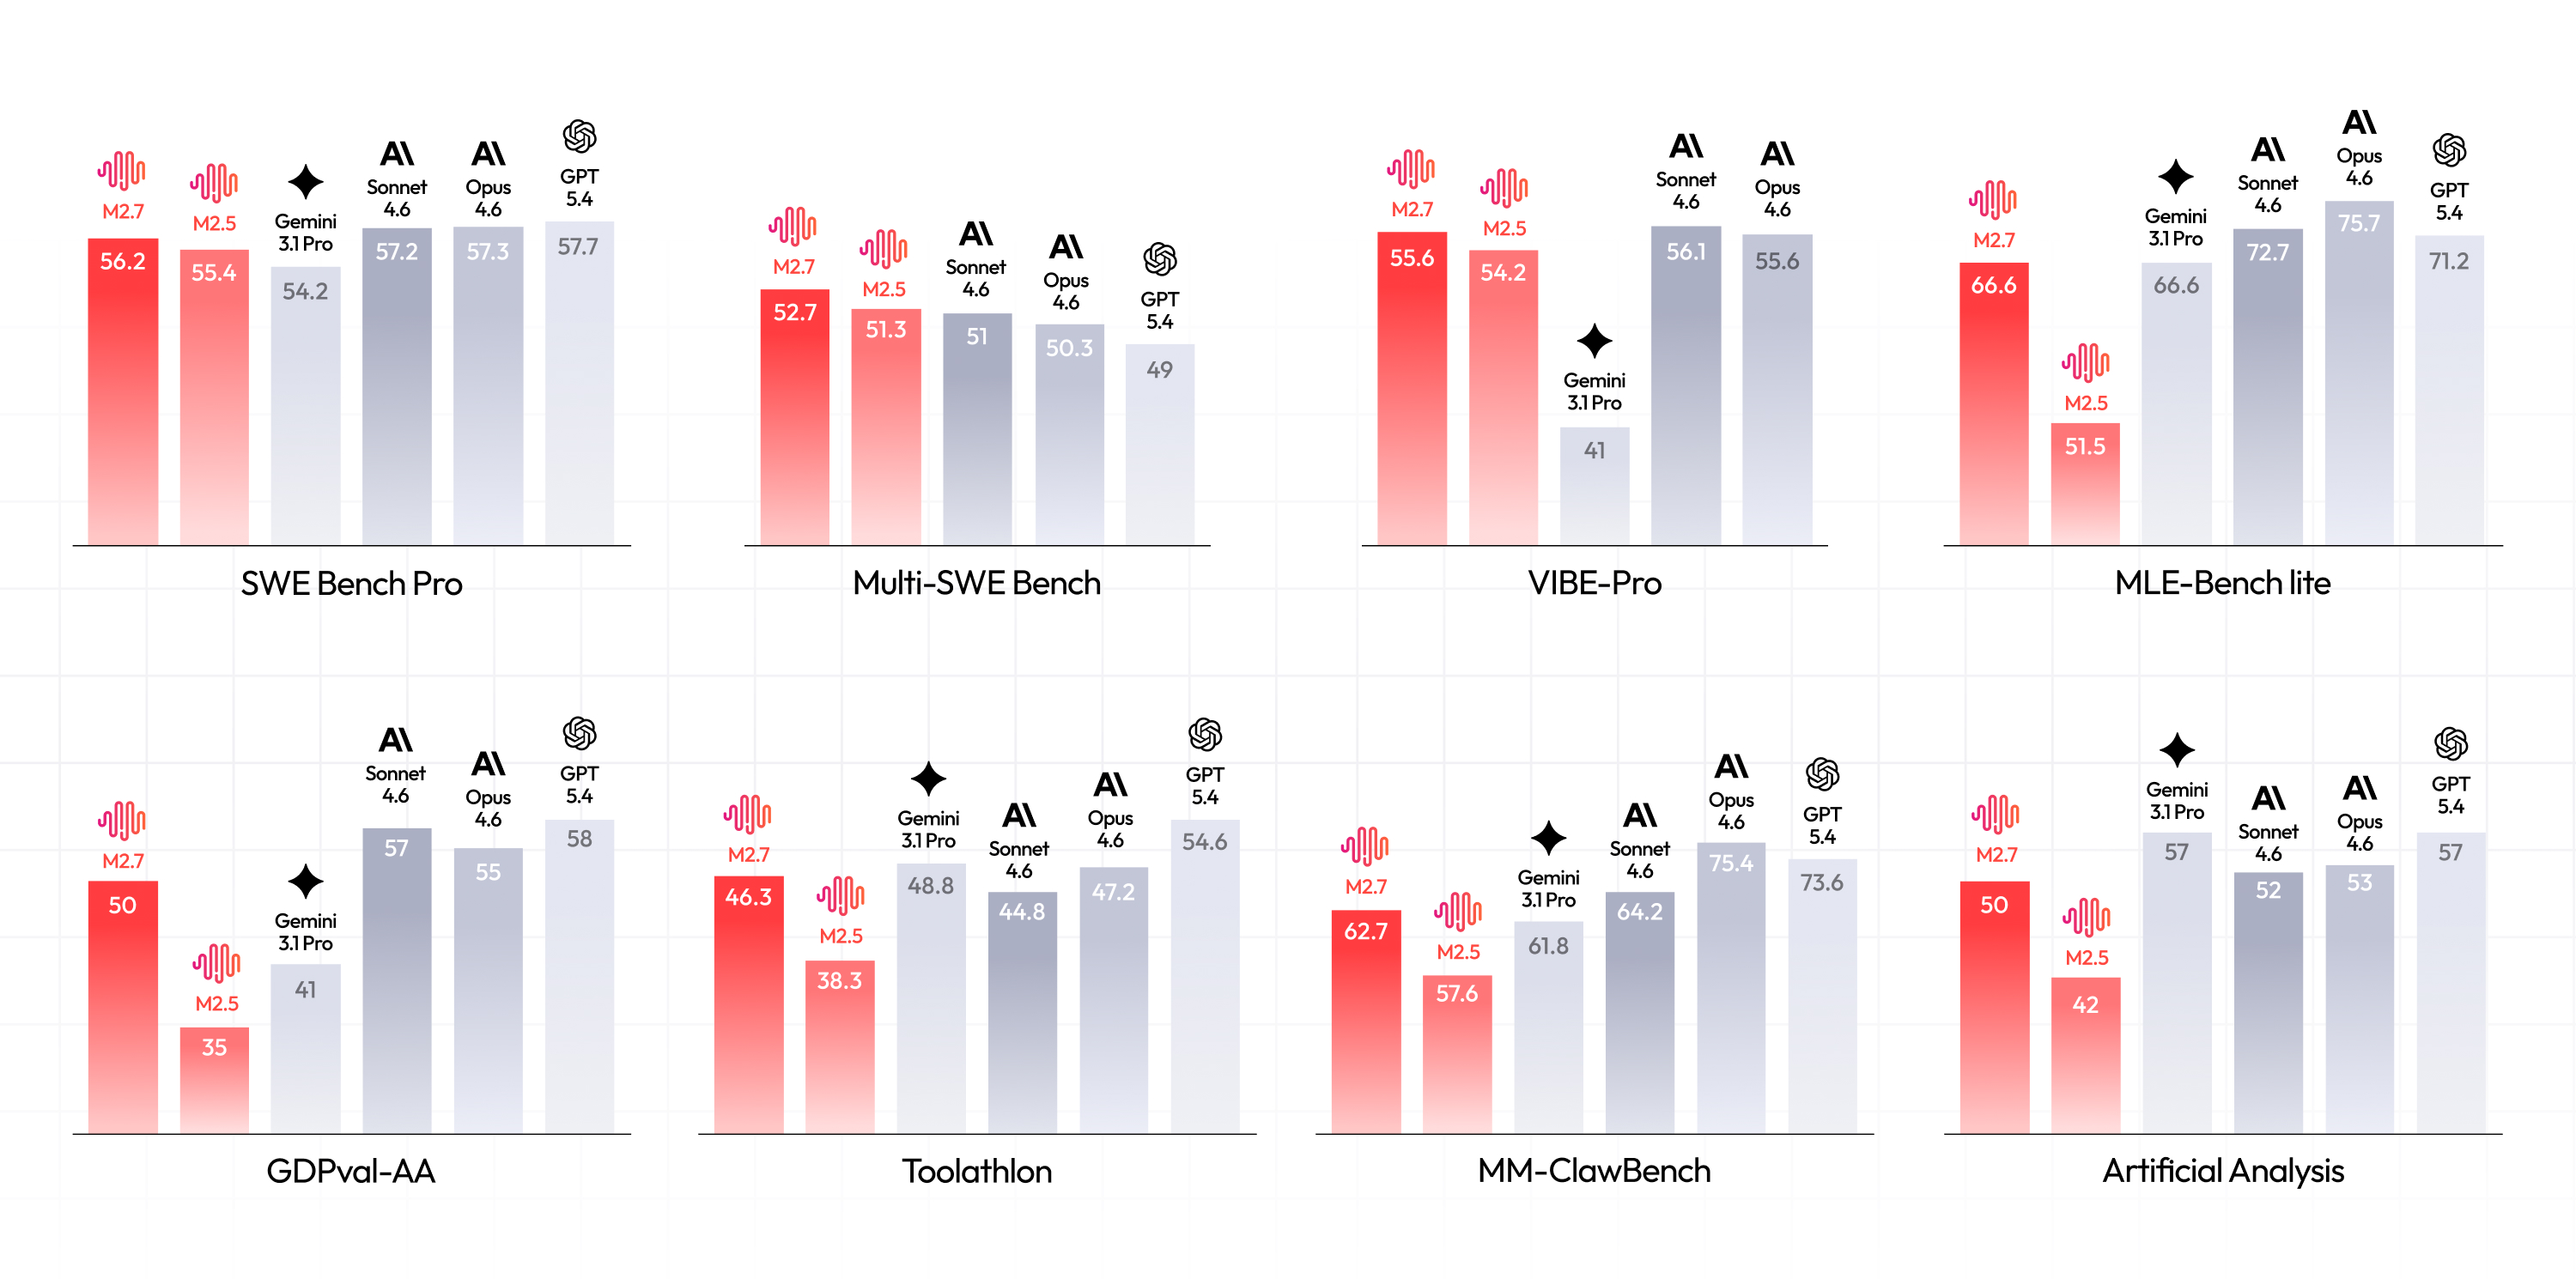
The newest model with a score here came out in March 2026, and nobody has tested a newer one. Among the 20 highest-ranked models on the capability index, these have no score yet:
- Claude Fable 5.2
-
 Gemini 4 Carbon
- GPT-6 Astra
- Claude Opus 5.5
- and 16 more
- 1 Claude Opus 4.6 75.4%
- 2 GPT-5.4 73.6%
- 3 Claude Sonnet 4.6 64.2%
- 4
 MiniMax-M2.7 62.7%
- 5 Gemini 3.1 Pro 61.8%
- 6 MiniMax-M2.5 57.6%
Source: Official MM-ClawBench leaderboard
| # | Model | Score | Setting | Date | Source |
|---|---|---|---|---|---|
| 1 | Claude Opus 4.6 | 75.4% | Feb 2026 | Official leaderboard | |
| 2 | GPT-5.4 | 73.6% | Mar 2026 | Official leaderboard | |
| 3 | Claude Sonnet 4.6 | 64.2% | Feb 2026 | Official leaderboard | |
| 4 | MiniMax-M2.7 | 62.7% | Mar 2026 | Official leaderboard | |
| 5 | Gemini 3.1 Pro | 61.8% | Feb 2026 | Official leaderboard | |
| 6 | MiniMax-M2.5 | 57.6% | Feb 2026 | Official leaderboard |
Labs report scores for 2 models in their cards. We plot every source in the charts below.
Number one over time
Lab claims count from the day the card came out, independent runs from the model’s release. We draw one row each for the benchmark’s own leaderboard and what labs claim in their cards.
Sources: Official MM-ClawBench leaderboard and labs’ model cards
Scores over time
All the scores we have, one dot each, so a model tested at several settings appears more than once.
Sources: Official MM-ClawBench leaderboard and labs’ model cards
Labs headline it less often now, last in March 2026
Launch posts from every lab that has listed it, one tick per post. Tall colored ticks include it, and short gray ones leave it out.
| Date | Launch post | Score | As the post writes it |
|---|---|---|---|
| Mar 18, 2026 | MiniMax-M2.7 | 62.7 | MM-ClawBench (MM Claw) |
2 system cards report it, from 1 lab
Besides launch posts, we read the system cards, model cards and technical reports labs publish with a release. They report far more, including safety and frontier-risk tests.
| Date | Document | Score | As the document writes it | Section |
|---|---|---|---|---|
| May 26, 2026 | MiniMax-M2.7 technical report | 62.7 | MM Claw (Table 4) | Capabilities |
| May 26, 2026 | MiniMax-M2.5 technical report | 57.6 | MM Claw (Table 4) | Capabilities |
2 lab claims next to the leaderboard
Each score a lab reported for its own model, beside the same model's best score on the leaderboard. Gaps mostly come from different harnesses, effort levels and task subsets. 2 of them match, which usually means one side copied the other. Every benchmark.
| Model | Lab says | Board says | Gap |
|---|---|---|---|
| MiniMax-M2.7 | 62.7% MM-ClawBench (MM Claw) | 62.7% Leaderboard | Same |
| MiniMax-M2.5 | 57.6% MM Claw (Table 4) | 57.6% Leaderboard | Same |
More in Tool use
- AutomationBench In use Agent completes end-to-end business workflows inside a simulated company exposing dozens of REST APIs. Graded on resulting state. Gemini 4 Carbon 53.9%
- MCP Atlas In use Multi-step workflows over real MCP servers. Scores tool-use competency on realistic tasks. Gemini 4 Argon 90.7%
- BFCL V4 In use Models call functions and tools, including multi-turn agentic tasks with web search and memory. Checked against expected calls and outcomes.
 Qwen3.7-Max 75%
- τ³-bench Banking In use Agents act as banking customer-service reps over many turns with a simulated user, following policy. Pass^1 on the final database state. Qwen 3.8 Max 55.1%
- Toolathlon-Verified In use 108 long-horizon tasks across 32 apps through about 600 MCP tools. Execution-based checkers inspect final environment state. GLM-5.3-Flash 78.4%
- DeepSearchQA In use Questions that need multi-step search and synthesis. Final answers graded against references. Kimi K3 95%