AI-Spire (AGI-Eval)
Models replay one Slay the Spire 2 seed, build decks, and choose combat moves. The organizers record the floor reached on each attempt.
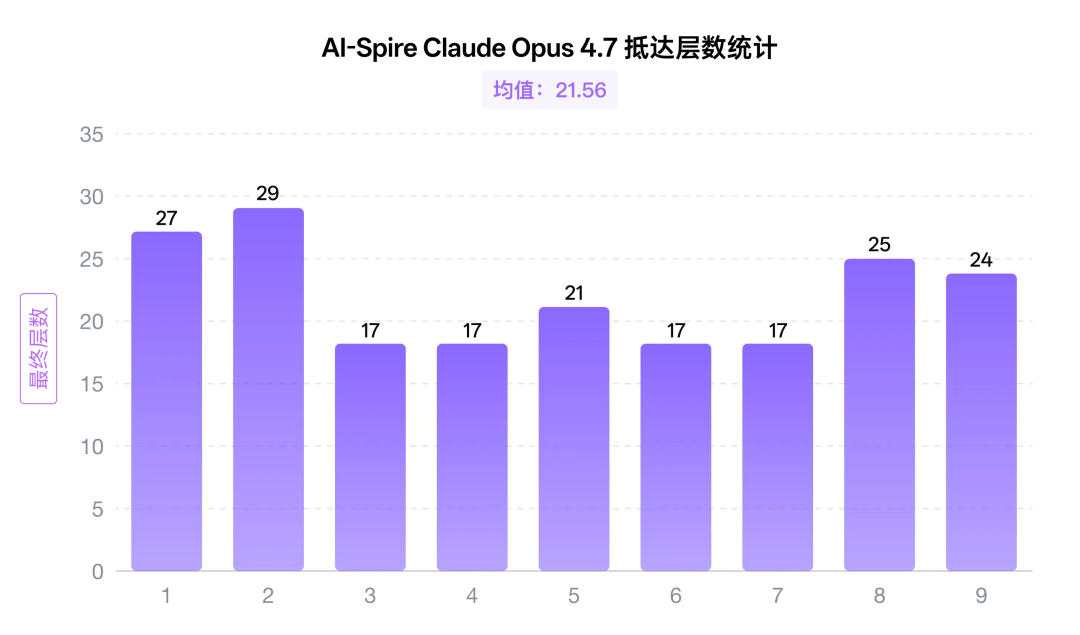
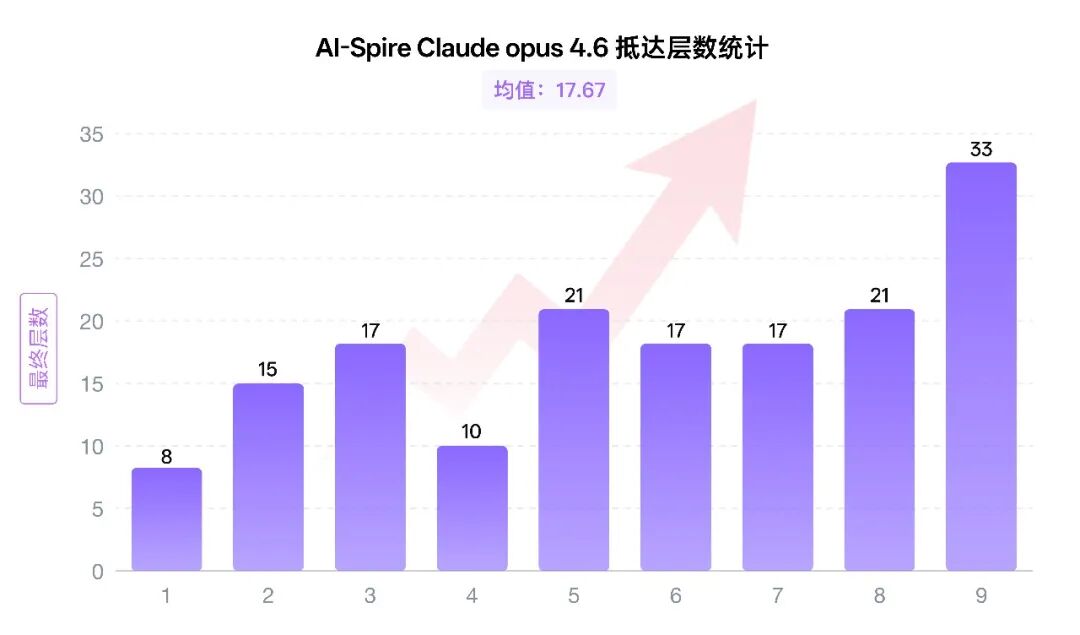
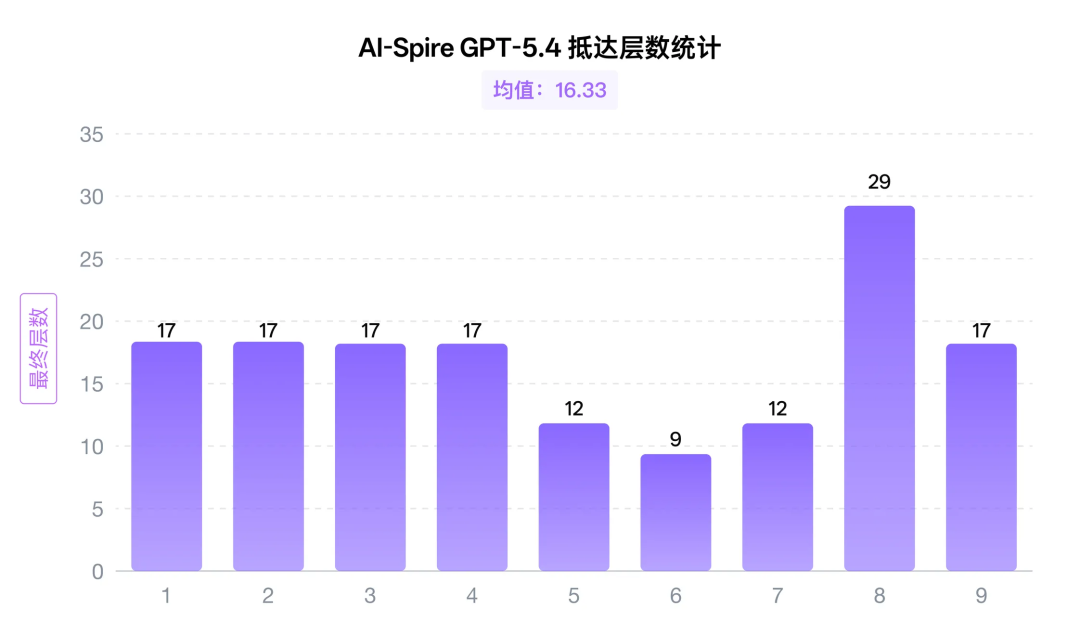
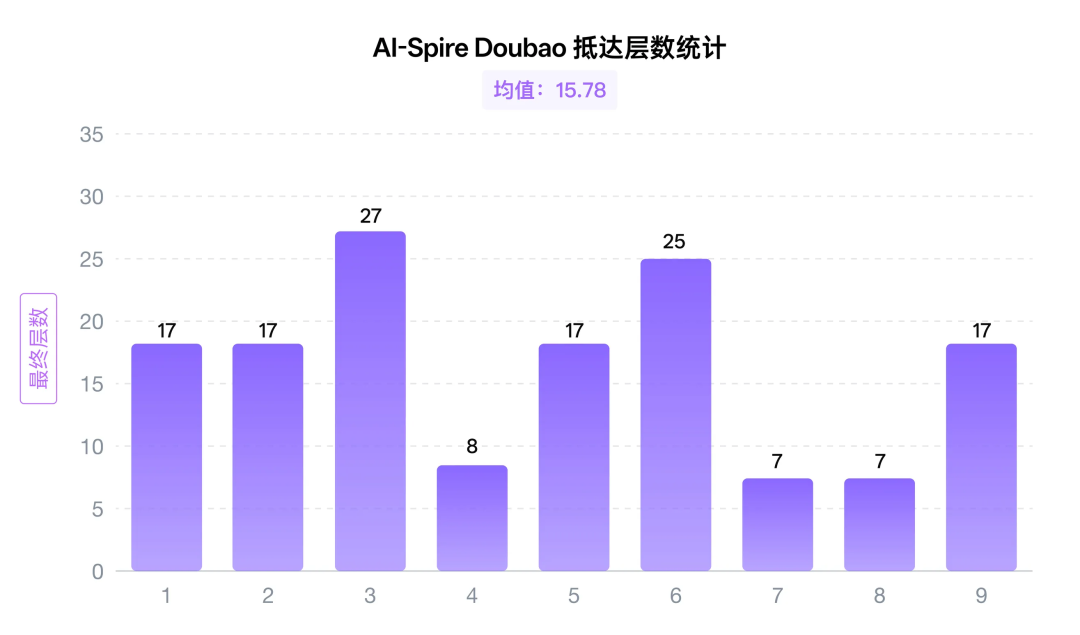
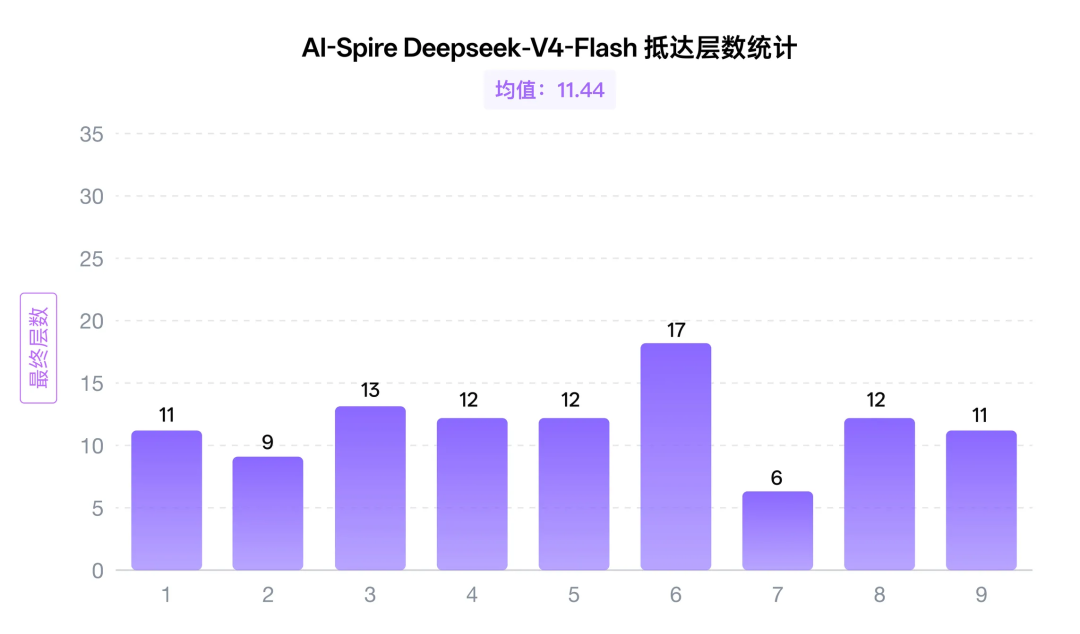
The organizers publish nine attempts for each of five models. Claude Opus 4.7 averaged 21.56 floors. Claude Opus 4.6 reached floor 33 on its ninth attempt.
- Made by
- AGI-Eval Community
- Released
- May 2026
- Kind
- Video games
- Level
- Everyday
- Scored
- Checked automatically
- Answers
- Agent task
- Measures
- Capability
- Language
- Chinese
- Interaction
- Multi-agent
- Environment
- Slay the Spire 2
- Items from
- Generated
- Refresh
- One fixed set
- Run by
- A host
- Strongest model tested
- GPT-5.4 #28 on the capability index
- Last model added
- April 2026
- Scores refreshed
- November 20th, 2026
Claude Opus 4.7 leads with 21.6 among models released by April 2026 Claude Opus 4.7 leads with 21.6 among models released by April 2026
Best score per entry from the benchmark's own leaderboard, read on November 20th, 2026. Where a model ran with several settings or harnesses, we keep its best. Names in gray aren't in our model list: fine-tunes, agent systems, products and older models. They don't count toward leaders. This view shows only models we track, each at its best.
The newest model with a score here came out in April 2026, and nobody has tested a newer one. Among the 20 highest-ranked models on the capability index, these have no score yet:
- GPT-6.2 Astra
- Claude Fable 5.2
-
 Gemini 4 Carbon
- GPT-6 Astra
- and 16 more
- 1 Claude Opus 4.7 21.6
- 2 Claude Opus 4.6 17.7
- 3 GPT-5.4 16.3
- 4 Doubao 15.8
- 5
 DeepSeek-V4-Flash 11.4
Source: Official AI-Spire (AGI-Eval) leaderboard
- 1 Claude Opus 4.7 21.6
- 2 Claude Opus 4.6 17.7
- 3 GPT-5.4 16.3
- 4 DeepSeek-V4-Flash 11.4
Source: Official AI-Spire (AGI-Eval) leaderboard
| # | Entry | Score | Setting | Date | Link | Source |
|---|---|---|---|---|---|---|
| 1 | Claude Opus 4.7 | 21.6 | Apr 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 2 | Claude Opus 4.6 | 17.7 | Feb 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 3 | GPT-5.4 | 16.3 | Mar 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 4 | Doubao | 15.8 | i-blog.csdnimg.cn | Official leaderboard | ||
| 5 | DeepSeek-V4-Flash | 11.4 | Apr 2026 | i-blog.csdnimg.cn | Official leaderboard |
| # | Model | Score | Setting | Date | Link | Source |
|---|---|---|---|---|---|---|
| 1 | Claude Opus 4.7 | 21.6 | Apr 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 2 | Claude Opus 4.6 | 17.7 | Feb 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 3 | GPT-5.4 | 16.3 | Mar 2026 | i-blog.csdnimg.cn | Official leaderboard | |
| 4 | DeepSeek-V4-Flash | 11.4 | Apr 2026 | i-blog.csdnimg.cn | Official leaderboard |
Number one over time
Lab claims count from the day the card came out, independent runs from the model’s release.
Source: Official AI-Spire (AGI-Eval) leaderboard
Scores over time
All the scores we have, one dot each, so a model tested at several settings appears more than once.
Source: Official AI-Spire (AGI-Eval) leaderboard
No lab model card reports it yet
We read the headline results of 540 launch posts from 57 labs, and none of them list this benchmark.
More in Games and long tasks
- ARC-AGI-3 In use Interactive game environments where agents must explore, infer goals and rules, and act efficiently without instructions. GPT-6.2 Astra 100%
- Orak Fading LLM agents play 12 popular video games across most genres through an MCP interface. Each game scores in-game progress or outcomes, and the board ranks models by their average rank across the games. Gemini 2.5 Pro 3.90
- MineDojo Fading Agents complete open-ended tasks in Minecraft, such as mining blocks and fighting mobs, from a large simulation suite. Programmatic checks score many tasks.
 Seed2.0 Pro 49%
- TextQuests Only in system cards Agents play 25 classic interactive fiction games. The score is harmful actions per 100 steps, where lower is better. The board also reports game progress.
 Llama 4 Scout 7.00
- GameWorld Only in system cards Multimodal game agents play 34 browser games across 170 tasks. Outcomes are checked from the game state. GPT-6.1 Terra 76.8%
- Swarm Bench Only in system cards Models orchestrate agent swarms on complex tasks that benefit from coordinated decomposition and parallel execution. Kimi K3 76.3%
Data audit
7 of 9 checks pass, 2 warnings. Look first at the Task access check. We don’t know whether the tasks are public. Every benchmark
Catalog record 1 warning 1 pass
- Warning Task access We don’t know whether the tasks are public.
- Pass Confidence Checked against a primary source.
Scores 1 warning 2 pass 2 notes
- Pass Independent runs Scores from the official leaderboard (5 entries).
- Pass Models scored 4 models we track, plus 1 other entry on its leaderboard.
- Warning Newest score The newest came 7 months ago, in April 2026, for DeepSeek-V4-Flash.
- Note Frontier models None of the top 10 has a score. The strongest tested is GPT-5.4 (#28).
- Note Headroom Scored as a plain number, with no fixed ceiling.
Leaderboard import 3 pass
- Pass Importer We read the board on agent.csdn.net: 4 rows for models we track and 1 other entry at the last read.
- Pass Last read November 20th, 2026.
- Pass Read worked The last read worked.
Consistency 1 pass 1 note
- Note Lab claims No model has both a lab number and an independent run.
- Pass Known issues No published audit found problems.